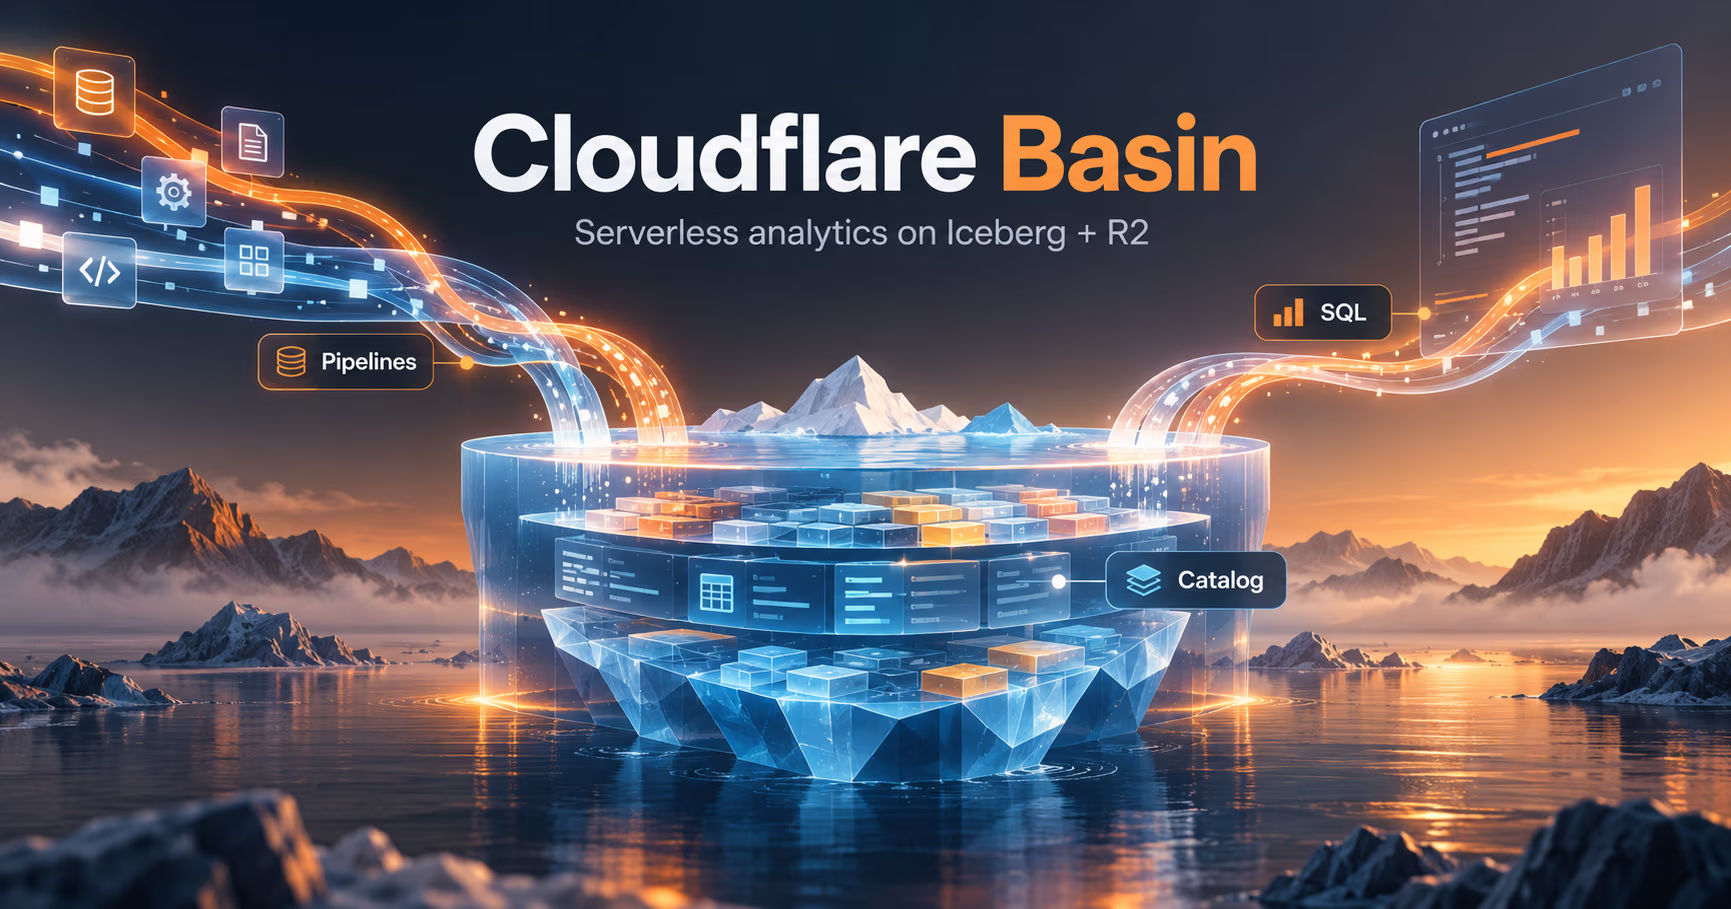
In October 2026, Cloudflare took the products it had been calling the Cloudflare Data Platform, gave them a new name, and flipped every one of them to generally available.
The three pieces, Basin Pipelines, Basin Catalog, and Basin SQL, form a serverless analytics stack built on two open things: Apache Iceberg, the table format, and R2 object storage underneath.
This post is the sysadmin read on the announcement. What Basin actually is, how Pipelines, Catalog, and SQL fit together, the CLI commands that matter, the honest limits, and where the platform still has gaps.
If you have been watching since the Birthday Week 2025 beta, most of this is a rename plus a maturity pass; if you have not, this is the state of a managed Iceberg lakehouse that lives inside the Worker platform.
The short version
- Basin is the GA name for the Cloudflare Data Platform. Cloudflare Pipelines, R2 Data Catalog, and R2 SQL are now Basin Pipelines, Basin Catalog, and Basin SQL. Existing resources and configurations keep working.
- The stack is Iceberg on R2. Pipelines ingests and transforms events, Catalog manages Iceberg table metadata and maintenance, SQL runs distributed queries. Storage stays in your R2 bucket, so egress is free and any Iceberg-compatible engine (PyIceberg, DuckDB, Snowflake, Spark) can read and write your data.
- Pipelines transforms as it ingests. Events arrive via HTTP, Worker bindings, or Cloudflare Logpush, are reshaped by a SQL query, and land as Iceberg tables or JSON or Parquet files in R2, with per-stream ingest capacity in the gigabyte-per-second range.
- Catalog does the housekeeping you used to run Spark for. Automatic compaction, snapshot expiration, unreferenced data cleanup, and manifest optimization, all on a managed Iceberg REST catalog.
- SQL is a serverless distributed engine, not a cluster. No provisioning; run from Wrangler, the API, or a dashboard editor, with joins, window functions, QUALIFY, and more than 190 scalar and aggregate functions.
- Billing is usage-based. You pay when Basin ingests, processes, or queries your data. No hourly charges, no separate infrastructure. Hobby-scale analytics can be near free, heavy analytics scale with volume.
- Cloudflare announcement
Introducing Cloudflare Basin, Oct 1 2026 - Basin docs overview
developers.cloudflare.com/basin, updated Oct 1 2026 - Basin docs changelog
entries for Oct 1, Sep 16, Aug 3, Jul 13 2026
Why Basin?
The name is deliberate and physical.
A basin is where rivers from many sources converge into a single point, and Cloudflare borrowed the metaphor: Pipelines brings data in, Catalog holds it as Iceberg tables, SQL makes it instantly queryable.
The team also points out that roughly 20% of Earth's land drains into endorheic basins, which they compare to the share of the web behind Cloudflare's network. The visual is cute; the rename does real work, because it turns three separately shipped betas into one product line with a story.
The deeper justification is a data-architecture argument, not a branding one. Two developments convinced Cloudflare the moment was right. Apache Iceberg became the standard open table format, making data portable across nearly every serious query engine. And developers started putting analytics data in R2, where the absence of egress charges made it practical, and cheap, to access that data from different tools, teams, regions, and cloud providers.
Basin is the answer to that pattern: separate storage from compute, keep the storage open and portable, and charge only for the work done on it.
The three products, and what they renamed from
Before (beta) | Now (GA) | Job |
|---|---|---|
Cloudflare Pipelines | Basin Pipelines | Ingest events, transform with SQL, write Iceberg tables or JSON/Parquet files |
R2 Data Catalog | Basin Catalog | Iceberg REST catalog, metadata, and automatic table maintenance |
R2 SQL | Basin SQL | Serverless distributed SQL engine over Iceberg tables in R2 |
Existing Pipelines, R2 Data Catalog, and R2 SQL setups keep working under the new names, so the rename is safe for current users.
Basin Pipelines: transform at ingest
Pipelines sits at the front of the stack. It receives events through HTTP endpoints or Workers bindings (and Cloudflare Logpush, if you point your logs at a Pipeline), transforms them according to a SQL query, and delivers the result to Basin Catalog as Apache Iceberg tables, or to R2 as JSON or Parquet files.
The pitch is doing the work during ingestion rather than after. Cloudflare's own example filters HTTP logs before they are stored, which shrinks the footprint, cuts noise from dynamic fields, and can keep sensitive values out of the table entirely:
INSERT INTO http_logs_sink
SELECT
  EdgeResponseStatus,
  to_timestamp_micros(EdgeStartTimestamp) AS event_time,
  upper(ClientRequestMethod) AS method,
  sha256(ClientIP) AS hashed_ip
FROM http_logs_stream
WHERE EdgeResponseStatus >= 400;
Since the beta, the pipeline surface has grown in ways that matter operationally:
- Schema-aware Worker bindings. Running
wrangler typesgenerates TypeScript types from a stream's schema, so missing fields and type mismatches surface before deployment, not in your warehouse. - Visible data quality errors. The dashboard and GraphQL API show dropped events and distinguish missing fields, type mismatches, parse failures, and null values. That distinguishes signal from the usual silent-skip behavior.
- Everything is infrastructure as code. Terraform resources cover the catalog, the stream, the sink, and the SQL connecting them.
- Logpush integration. Cloudflare logs can be transformed with SQL and stored as compressed Parquet or Iceberg tables, ready for Basin SQL or another engine.
The ingest limit is the number to watch: the announcement claims up to 3 GB/s per stream, while the Basin docs changelog for the same day (https://developers.cloudflare.com/basin/#changelog-heading) states 1 GB/s per stream, raised from 5 MB/s during beta. Either way it is a large jump from beta, and the gap between the two figures is a reason to check current limits before you size anything.
Basin Catalog: Iceberg maintenance without a Spark job
Catalog is the managed Iceberg REST catalog for an R2 bucket, and it is the easiest on-ramp into Basin. The announcement shows the one-liner:
$ npx wrangler basin pipelines setup

# enable Basin Catalog on an existing R2 bucket
$ npx wrangler basin catalog enable YOUR_BUCKET_NAME

# the announcement's equivalent create form
$ npx wrangler basin catalog create CATALOG_NAME

# query a table straight from the CLI
$ npx wrangler basin sql query YOUR_WAREHOUSE_NAME "SELECT * FROM default.events LIMIT 10"
What you get for that command is a catalog that performs the routine maintenance that otherwise means standing up Spark jobs:
- Per-table compaction policies, so you can target file sizes based on each table's access pattern instead of running one big compaction for everything.
- Automatic snapshot expiration, which drops old Iceberg snapshots according to a retention policy while preserving a minimum number of recent ones.
- Unreferenced data-file cleanup, reclaiming storage when snapshots expire without a separate maintenance job.
- Manifest optimization, consolidating and clustering fragmented manifests by partition before compaction, which cuts metadata I/O during query planning.
Cloudflare reports thousands of developers using Catalog in beta, from giving DuckDB a structured way to read analytics data out of R2, to full enterprise data-sharing platforms built on the free-egress model. Catalog is also where compliance work is heading: jurisdiction support for data sovereignty is on the roadmap.
Basin SQL: the query layer with no cluster
Basin SQL is the serverless, distributed engine for Iceberg tables in Basin Catalog. There are no clusters or resources to provision, just an API (or the CLI, or a dashboard editor with autocomplete, a namespace browser, query stats, plans, and exportable results).
At beta launch it was good at filtering and exploring large event tables. A year later it supports a relational feature set that covers most analytic workloads:
- Standard and approximate aggregations, GROUP BY, HAVING, and schema-discovery commands
- More than 190 scalar and aggregate functions across strings, timestamps, regex, crypto, statistics, arrays, maps, and structs
- CASE expressions, CTEs, casting, arithmetic, and EXPLAIN
- Inner, outer, semi, and anti joins; subqueries; self-joins; multi-table queries
- DISTINCT, UNION, INTERSECT, EXCEPT
- Window functions, QUALIFY, grouping sets, rollups, and cubes
- A suite of JSON functions
The announcement's second example shows the analytical level it is aiming at: join events to account data, aggregate activity by plan, rank accounts with a window function, and filter the ranking in one query:
WITH account_activity AS (
  SELECT
    a.plan,
    e.account_id,
    count(*) AS events,
    approx_distinct(e.user_id) AS active_users
  FROM analytics.events e
  JOIN analytics.accounts a ON e.account_id = a.account_id
  WHERE e.event_time >= '2026-09-01T00:00:00Z'
  GROUP BY a.plan, e.account_id
)
SELECT *, rank() OVER (PARTITION BY plan ORDER BY events DESC) AS activity_rank
FROM account_activity
QUALIFY rank() OVER (PARTITION BY plan ORDER BY events DESC) <= 10;
Cost model: pay for work, not for servers
The pricing model is the piece that makes Basin different from renting a Spark cluster or an Athena-on-demand bill that charges by the terabyte scanned. Because everything is serverless, Cloudflare bills only when Basin ingests, processes, or queries data. There are no hourly charges and no separate infrastructure line items, which is how hobby analytics can run at little to no cost while enterprise-scale usage scales economically.
The other cost lever is egress. R2 charges no egress fees, and because Iceberg decouples storage from compute, you can read and write your datasets with any Iceberg-compatible engine regardless of vendor or region. Anomaly's co-founder describes exactly that migration: the company moved its entire data pipeline from a complex AWS S3 and Athena setup to Basin's cleaner serverless architecture. Bobsled, a data product platform, says Basin lets it build data products reachable in any region of every major data and AI platform at a fraction of the cost thanks to zero egress fees.
One caveat for non-enterprise accounts: billing for all three services was enabled in August 2026, so the free tiers have bounds, and usage beyond them appears on the next invoice. Budget for ingest and query volume, not for idle capacity, and per the limit note above, confirm current per-stream and per-catalog limits before you commit to a number.
What comes next
The announced roadmap is worth tracking if you are evaluating Basin seriously:
- Support for the latest Apache Iceberg spec across the platform; the product roadmaps list Iceberg V3 with the VARIANT type for Pipelines and SQL, and geospatial types for SQL
- Full data definition language (DDL) directly from Basin SQL, and more SQL compatibility and observability
- Push-button ingestion sources and destinations with zero-configuration connections across Cloudflare's developer and observability products
- Adaptive, query-pattern-driven table maintenance in Catalog (plus more granular auth controls and jurisdiction support)
- Stateful processing for streaming aggregations, joins, and incrementally updated materialized views
- More ways to process data continuously in real time and trigger actions on signals in the data
- Pipelines-specific: custom partitioning when writing to Basin Catalog, plus schema migrations and updatable configuration and Pipelines SQL
- Catalog-specific: a new approach to compaction that sorts and clusters data for query performance
- SQL-specific: advanced statistics and adaptive scheduling to improve query performance and efficiency
The honest gaps
- The ingest limit discrepancy. 3 GB/s per stream per the announcement versus 1 GB/s per the same-day changelog is a real ambiguity for anyone sizing a pipeline. Cloudflare's own billing and infrastructure teams are early users, which is a vote of confidence, but check the limits page.
- DDL and Iceberg V3 are not here yet. Basin SQL reads and queries data today; full self-serve schema management and the Iceberg V3/VARIANT world are still roadmap items.
- The catalog is young for heavy governance. Namespace and table-level auth controls are being worked on, along with jurisdiction support. If you need fine-grained multi-tenant access control or strict data residency now, keep your local Iceberg catalog skills warm.
- Billing is newly live. The free tiers have stated bounds now that August 2026 billing took effect on non-enterprise accounts. Oversight of ingest and query volume matters more than it did in beta.
Who is this for?
- Teams already storing analytics in R2. If your data is in R2 and you have been bolting on DuckDB or a catalog, Basin formalizes the path with managed metadata and maintenance.
- Anyone tired of Athena and S3 egress bills. The Anomaly example is the template: replace a multi-vendor lakehouse with one serverless stack where moving data out costs nothing.
- Worker platform users. Pipelines binds to Workers, Wrangler generates types from stream schemas, and SQL is an API call away. If your stack is already Cloudflare-shaped, Basin is the analytics layer that fits.
- Hobbyists and small teams. Usage-based pricing with free tiers means a personal analytics project can run cheap without you babysitting a cluster, similar to the BaaS versus FaaS trade-offs we covered before.
Official sources
- Cloudflare Basin announcement: https://blog.cloudflare.com/cloudflare-basin/
- Basin docs overview: https://developers.cloudflare.com/basin/
- Basin docs What's-new changelog (GA, ingest-limit, and billing entries): https://developers.cloudflare.com/basin/#changelog-heading
- Basin Pipelines documentation: https://developers.cloudflare.com/basin/pipelines/
- Basin Catalog documentation: https://developers.cloudflare.com/basin/catalog/
- Basin SQL documentation: https://developers.cloudflare.com/basin/sql/
- Basin CLI guide: https://developers.cloudflare.com/basin/get-started/guide/
- Our Worker Previews post, the other recent Cloudflare developer platform change: https://systhoughts.com/posts/cloudflare-worker-previews-isolated-environments-per-git-branch
- Our BaaS vs FaaS comparison: https://systhoughts.com/posts/baas-vs-faas-light-self-hosting-supabase-appwrite-alternatives
Are you running analytics on R2 today, and does Basin's managed Iceberg layer change what you would build? And if you have hit the ingest limit discrepancy on a real pipeline, that is the comment this post needs.
Until next time, keep your systems thoughtful.
No comments yet